High-performance compute. Hosted in Ireland.
Dedicated NVIDIA Blackwell GPUs, or open models through one API. Both run on hardware we operate in Ireland.
Your own GPUs, or our model API.
Same hardware, same Irish sites, same zero-retention terms. Choose dedicated capacity you control, or call open models by the token.
Dedicated sovereign compute
Your own physically isolated RTX PRO 6000 GPUs, hosted in Ireland and operated by us. For work where data privacy, compliance and performance are not negotiable.
- Physically isolated, single-tenant hardware
- Inference and data stay in Ireland
- Zero data retention by design
- Fixed monthly or contracted pricing
- Any model, full control over the stack
- Bare metal, private AI and the API on one account
Sovereign model API
Open models behind one OpenAI-compatible API, on our own GPUs in Ireland. Switch from a closed frontier API by changing one line, and pay a fraction of the price.
- Drop-in OpenAI compatibility: one line of code
- A fraction of the cost of closed frontier APIs
- The right open model for each job, not one size for all
- Zero data retention on every request
- Pay per token, or commit to a monthly volume
- Shared API, or a dedicated endpoint when you grow
Sovereign by default
Inference and data stay in Ireland, under EU jurisdiction. Zero data retention: prompts and outputs are never stored or used for training.
Dedicated when it matters
Whole GPUs, never sliced or oversubscribed, for bare metal and dedicated endpoints. Start on the shared API and move to your own hardware on the same API.
Priced below the frontier
Open models at a fraction of what closed frontier APIs charge. Contract rates for committed capacity and volume.
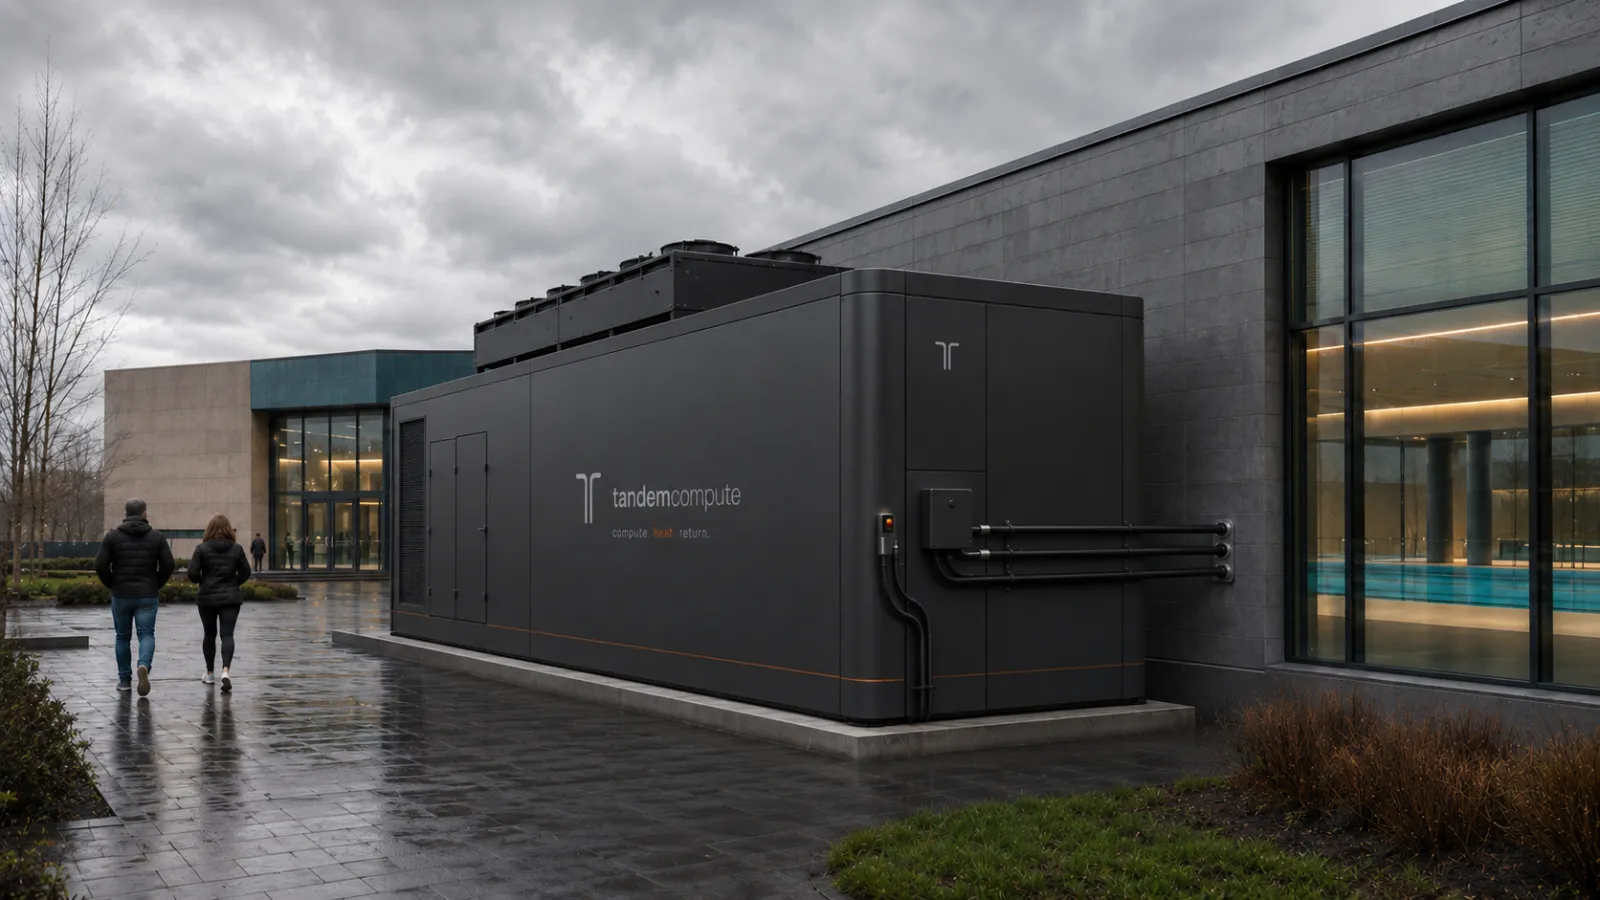
Every pod’s heat goes to the building beside it, so the same energy is used twice.
Accelerated compute, powered by NVIDIA.
One GPU across the fleet, so every site runs the same way. From a single card to whole liquid-cooled nodes.
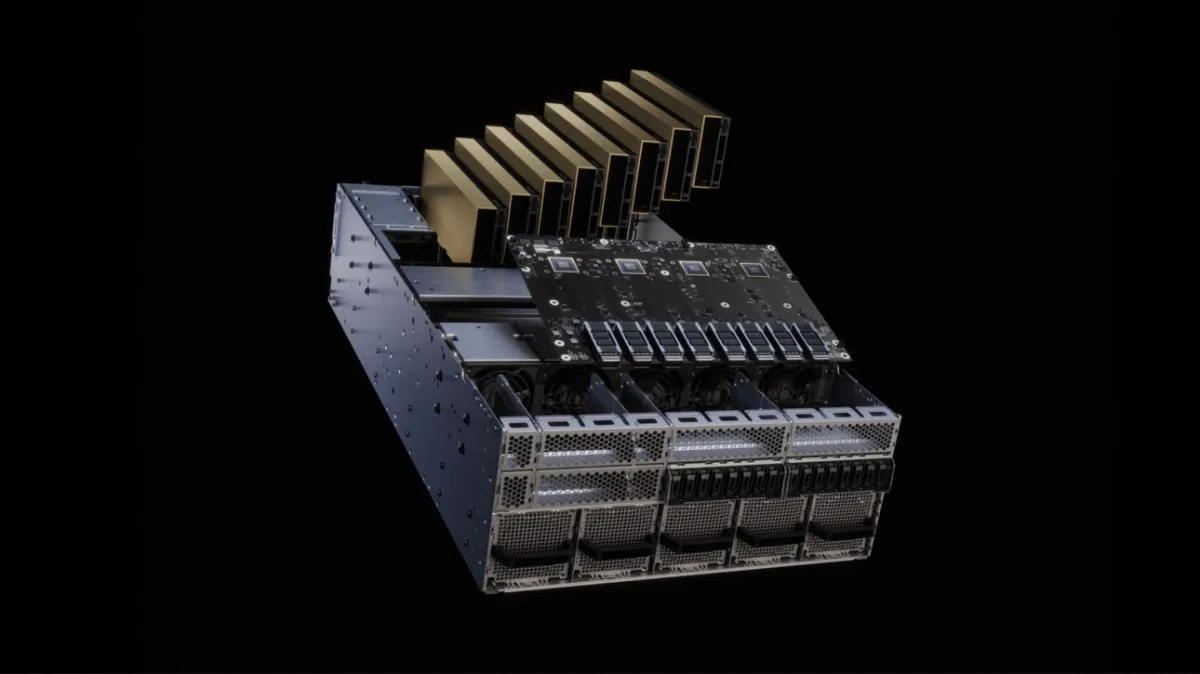
NVIDIA RTX PRO 6000 Blackwell
A universal GPU for AI inference, fine-tuning, rendering and simulation. 96 GB of memory with fifth-generation Tensor Cores and fourth-generation RT Cores, in Dell servers at every site.
More GPU types join the fleet as demand requires.
Open models, kept in Ireland.
An OpenAI-compatible API running the best open models on our own GPUs in Ireland. Your data never leaves the country and is never stored.
Data stays in Ireland
Inference runs on tandemcompute hardware in an Irish Tier III facility.
Zero data retention
Prompts and outputs are never stored, and never used for training.
Drop-in OpenAI compatibility
Point your existing OpenAI client at tandemcompute. One line of code changes.
A fraction of the cost
Well below closed frontier APIs, with the right model for each job.
Committed volumes
Monthly token commitments, or dedicated endpoints at contract rates.
One supplier
The same account covers bare metal, private AI and the API.
Indicative pricing on request. The flagships (GLM 5.3, Kimi K3, Qwen3.8-Max) run on dedicated endpoints at contract rates. See every model.
The rest of the pipeline, beside your GPUs.
CPU-only instances on the same private network as your GPU instances, so GPU capacity stays free for training and inference.
AI applications and agents
App backends, serving logic and orchestration that sit alongside your GPU workloads.
Data preprocessing
Tokenisation, feature engineering and data loading on dedicated CPU.
Offline and batch inference
Bulk evaluations, document processing and inference that is not latency-critical.
Automation and tooling
Evaluation harnesses, scheduled jobs, pipeline scripts and CI/CD.
More than instances. Run, build, scale.
Instances, storage and networking underneath. Models, jobs and private AI on top. All in Ireland, on infrastructure we operate.
Run
Serve and fine-tune models in production
Build
Train and serve custom models
Scale
Dedicated capacity in Ireland
RTX PRO 6000 Blackwell GPUs on Dell servers
The planned launch offering. Availability is confirmed as each site comes online.
Tell us what you are trying to run.
We will tell you what it takes.
One conversation covers capacity, contract pricing and your workload. Contracted capacity is allocated in order of enquiry as each site comes online.
Reply within two working days. No account, no card, no commitment.
Talk to us.
Tell us what you are trying to run, in plain language. We come back with how we would run it, when, and a price.